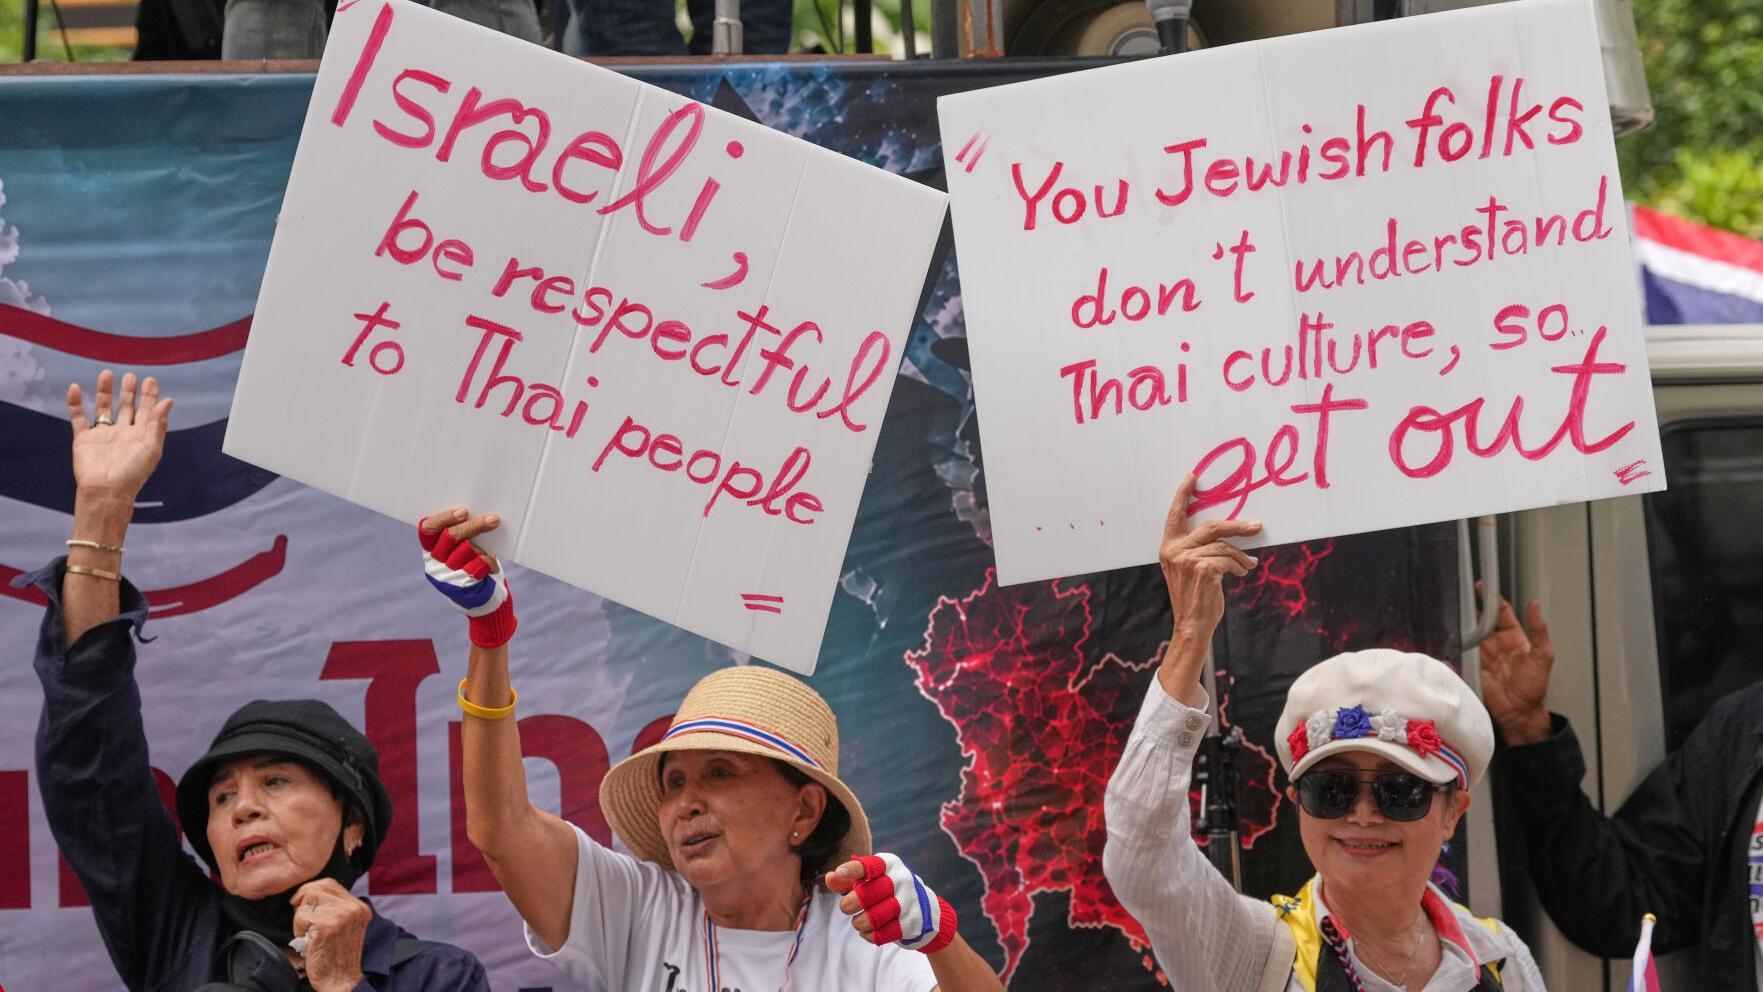
The Antisemitism Detection Suite includes a dataset of over 5000 human-annotated pieces of digital content, open models trained on this content, and the HateAPI. The HateAPI is a tool for classifying content based on our annotated data that plugs in to existing providers with optimized prompts and a unified interface.
Don't think he just rolled out of bed and started thinking about Jews.
Source
Why did Hitler become antisemi(...)
Post
>>542714850 No group of people that has interacted with Jews in any capacity likes them. The jews themselves are literally the only common denominator in antisemitism.
Attached image · included in classification
2 free example runs. No sign-in needed.
Compare models.
Decision benchmarks use 951 test posts. Each decision model shows its best binary F1 configuration. Cross-family cohorts differ.
Model
Median latency p50 · s
Evaluated input
API access
Self-host
Download prompt
Text
Context+
Image
Video frames▧
Native video
Qwen3.5 4B (AddressHate)
87.8
42.3
$0.49*
1.97
Text: Supplied figures; cohort unverified
Context: Supplied figures; cohort unverified
Image: Supplied figures; cohort unverified
Video frames: Supplied figures; cohort unverified
—
Qwen3.8 27B (AddressHate)
87.6
40.6
$3.46*
4.32
Text: Verified held-out test n=951; epoch 2 selected by validation loss before test evaluation. Different dataset revisions, prompts and media policies limit cross-family comparisons.
Context: Verified held-out test n=951; epoch 2 selected by validation loss before test evaluation. Different dataset revisions, prompts and media policies limit cross-family comparisons.
Image: Verified held-out test n=951; epoch 2 selected by validation loss before test evaluation. Different dataset revisions, prompts and media policies limit cross-family comparisons.
Video frames: Verified held-out test n=951; epoch 2 selected by validation loss before test evaluation. Different dataset revisions, prompts and media policies limit cross-family comparisons.
—
—
Gemma 4 12B (AddressHate)
84.5
33.4
$0.82*
3.25
Text: Supplied figures; cohort unverified
Context: Supplied figures; cohort unverified
Image: Supplied figures; cohort unverified
Video frames: Supplied figures; cohort unverified
—
—
Claude Opus 5.5
65.8
40.8
$28.18
3.83
Text: Supplied figures; cohort unverified
Context: Supplied figures; cohort unverified
Image: Supplied figures; cohort unverified
Video frames: Supplied figures; cohort unverified
—
—
GPT-6 Astra
59.0
35.9
$38.32
4.15
Text: Supplied figures; cohort unverified
Context: Supplied figures; cohort unverified
Image: Supplied figures; cohort unverified
Video frames: Supplied figures; cohort unverified
—
—
Nemotron 3.5 Super VL
55.5
32.7
$1.54
14.20
Text: Supplied figures; cohort unverified
Context: Supplied figures; cohort unverified
Image: Supplied figures; cohort unverified
—
—
Luna (Decisions)
50.4
30.4
$1.79
0.39
Text: Verified benchmark, test n=951
Context: Verified benchmark, test n=951
Image: Verified benchmark, test n=951
Video frames: Verified benchmark, test n=951
—
—
Jev 1.14
49.5
29.9
$0.63
0.31
Text: Verified benchmark, test n=951
Context: Verified benchmark, test n=951
Image: Verified benchmark, test n=951
Video frames: Verified benchmark, test n=951
—
—
Clef Omni
38.2
4.8
$4.42
1.52
Text: Verified benchmark, test n=951
Context: Verified benchmark, test n=951
Image: Verified benchmark, test n=951
Video frames: Verified benchmark, test n=951
Native video: Verified benchmark, test n=951
F1 scores are percentages; Concept F1 is micro F1. Luna, Jev and Clef Omni show the configuration with the best binary F1, with that configuration’s other metrics. Different cohorts are approximate comparisons.
Evaluated inputs describe benchmark or smoke evidence, not live route capabilities. Video frames are sampled images. Hover over or focus a check for its evidence; unknown metrics remain blank. Self-host links open model repositories and may require access. The Open filter excludes private repositories.
*Asterisked costs are compute estimates, not hosted API pricing: Gemma 4 12B and Qwen3.5 4B (AddressHate) are supplied GPU compute costs, and Qwen3.8’s $3.46 / 1k estimates A100 processing compute; model loading, uploads and training are excluded. Its held-out test covers 951 posts (912 text-only), with median latency 4.32 s including preprocessing and scoring. The released model has gated downloads on Hugging Face; no hosted BYOK route is offered.


 4chanHate beyond the caption